Research
Alignment Research
The Arcadia Alignment team is a group of alignment researchers based in London. We study the alignment techniques that frontier labs will take bets on, and evaluate them publicly.

Research Topics
"/><stop offset="0.4989224137931034" stop-color="rgb(168, 192, 179)"/><stop offset="1" stop-color="rgb(248, 250, 248)"/></linearGradient><linearGradient id="VxQIWVOWg-560894406-linear-gradient" x1="1" x2="0" y1="0.4974874371859296" y2="0.5025125628140704"><stop offset="0" stop-color="rgb(93, 123, 106)"/><stop offset="0.4970366379310345" stop-color="rgb(168, 192, 179)"/><stop offset="1" stop-color="rgb(248, 250, 248)"/></linearGradient></defs><path d="M 10.292 29.562 L 10.292 5.944 L 0 0 L 0 35.427 L 30.865 53.247 L 30.865 41.438 Z" fill="transparent" height="53.2472px" id="jRMbERZHY" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(2.246 40.56)" width="30.865310000000004px"/><path d="M 30.877 17.82 L 30.877 53.247 L 20.584 47.315 L 20.584 23.697 L 0 11.809 L 0 0 Z" fill="transparent" height="53.24720000000001px" id="pjjNDuG1t" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(43.404 17.09)" width="30.8765px"/><path d="M 32.764 5.944 L 10.292 17.18 L 0 11.236 L 22.472 0 Z" fill="transparent" height="17.179699999999997px" id="wJXDLogjn" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(2.246 29.326)" width="32.76401px"/><path d="M 53.348 17.82 L 42.382 23.303 L 30.877 29.056 L 0 11.236 L 22.472 0 Z" fill="url(%23DK1IIZkXg-560894406-linear-gradient)" height="29.05618px" id="DK1IIZkXg" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(43.404 5.855)" width="53.348400000000005px"/><path d="M 22.472 0 L 22.472 35.427 L 0 46.663 L 0 11.236 L 11.505 5.483 Z" fill="transparent" height="46.66289999999999px" id="nVZl2HeJa" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(74.279 23.674)" width="22.47189999999999px"/><path d="M 22.472 0 L 22.472 11.809 L 0 23.045 L 0 11.236 Z" fill="transparent" height="23.0449px" id="CUvDdoRcr" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(33.113 70.764)" width="22.471899999999998px"/><path d="M 43.045 11.876 L 20.573 23.112 L 0 11.236 L 22.472 0 Z" fill="url(%23VxQIWVOWg-560894406-linear-gradient)" height="23.1124px" id="VxQIWVOWg" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(12.541 58.887)" width="43.045px"/><path d="M 22.472 0 L 22.472 23.618 L 0 34.854 L 0 11.236 Z" fill="transparent" height="34.854000000000006px" id="HB_vdUjPU" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(12.541 35.27)" width="22.4719px"/></svg>)
Model Motivations
The effects of large-scale reinforcement learning on what models value and intend are little understood. We investigate how training shapes model motivations, and how it can erode alignment.
Model Motivations
The effects of large-scale reinforcement learning on what models value and intend are little understood. We investigate how training shapes model motivations, and how it can erode alignment.
Model Motivations
The effects of large-scale reinforcement learning on what models value and intend are little understood. We investigate how training shapes model motivations, and how it can erode alignment.
"/><stop offset="0.4823376885775862" stop-color="rgb(168, 192, 179)"/><stop offset="1" stop-color="rgb(248, 250, 248)"/></linearGradient></defs><path d="M 61.4 35.45 L 61.4 45.508 L 0 10.067 L 0 0 Z" fill="transparent" height="45.5083px" id="tZAWzmVFZ" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(2.084 46.533)" width="61.400020000000005px"/><path d="M 61.4 35.45 L 61.4 45.517 L 7.892 14.625 L 0.567 10.392 L 0 10.067 L 0 0 Z" fill="transparent" height="45.5167px" id="FgEnC9XV1" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(10.859 31.465)" width="61.4px"/><path d="M 16.667 0 L 16.667 10.058 L 0 18.392 L 0 8.333 Z" fill="transparent" height="18.39160000000001px" id="z5yVhNbuE" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(63.484 73.648)" width="16.666599999999995px"/><path d="M 61.4 35.45 L 61.4 45.517 L 7.9 14.625 L 0.575 10.4 L 0 10.067 L 0 0 Z" fill="transparent" height="45.5167px" id="jFswCRRsW" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(19.625 16.402)" width="61.400000000000006px"/><path d="M 16.667 0 L 16.667 10.067 L 7.325 14.733 L 0 18.4 L 0 8.333 L 7.325 4.675 Z" fill="transparent" height="18.4px" id="DDQZi5wk3" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(81.025 43.518)" width="16.66669999999999px"/><path d="M 78.067 35.45 L 68.725 40.125 L 61.4 43.783 L 0 8.333 L 16.667 0 Z" fill="url(%23YeB1D8XN1-3464913445-linear-gradient)" height="43.78334px" id="YeB1D8XN1" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(19.625 8.068)" width="78.0668px"/><path d="M 16.667 0 L 16.667 10.067 L 7.325 14.742 L 0 18.4 L 0 8.333 L 7.325 4.675 Z" fill="transparent" height="18.4px" id="XeZFsiy8d" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(72.258 58.582)" width="16.66669999999999px"/><path d="M 78.067 31.783 L 68.725 36.458 L 61.4 40.117 L 0 4.667 L 9.342 0 L 16.667 4.225 L 70.167 35.117 L 77.492 31.45 Z" fill="transparent" height="40.116699999999994px" id="O8iFw8E5s" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(10.859 26.799)" width="78.0668px"/><path d="M 78.067 31.792 L 61.4 40.125 L 0 4.675 L 9.342 0 L 16.667 4.233 L 70.175 35.125 L 77.5 31.467 Z" fill="transparent" height="40.125px" id="tvj9G81o4" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="1" stroke="rgb(0, 0, 0)" transform="translate(2.084 41.857)" width="78.06662px"/></svg>)
Scalable Oversight
We study how to apply scalable oversight techniques towards aligning models we might not be able to control.
Scalable Oversight
We study how to apply scalable oversight techniques towards aligning models we might not be able to control.
Scalable Oversight
We study how to apply scalable oversight techniques towards aligning models we might not be able to control.
"/><stop offset="0.5067012392241379" stop-color="rgb(168, 192, 179)"/><stop offset="1" stop-color="rgb(93, 123, 106)"/></linearGradient></defs><path d="M 8.509 3.667 L 0 7.921 L 0 0 C 2.991 1.728 5.825 2.947 8.509 3.667 Z" fill="transparent" height="7.920999999999992px" id="PQsxlbkXf" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(41.166 89.772)" width="8.508700000000005px"/><path d="M 0 0.737 L 1.474 0 C 0.974 0.21 0.482 0.465 0 0.737 Z" fill="transparent" height="1px" id="CEu1I7rHN" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(19.158 15.404)" width="1.4739000000000004px"/><path d="M 48.342 28.456 C 48.342 33.754 47.474 38.132 45.745 41.579 C 44.245 44.579 42.088 46.877 39.281 48.482 C 39.07 48.605 38.851 48.719 38.632 48.824 L 38.044 49.123 C 34.403 50.807 30.316 51.044 25.781 49.842 L 25.772 49.842 C 23.088 49.123 20.254 47.903 17.263 46.175 L 17.263 54.096 L 0 29.272 L 17.263 24.386 L 17.263 32.307 C 21.079 34.517 24.491 35.351 27.5 34.816 C 28.623 34.623 29.684 34.237 30.684 33.667 C 33.807 31.895 35.605 28.754 36.105 24.237 C 36.202 23.377 36.254 22.456 36.254 21.482 C 36.254 18.439 35.754 15.307 34.745 12.088 C 33.737 8.868 32.368 5.763 30.64 2.789 L 40.404 0 C 42.877 4.596 44.816 9.351 46.228 14.254 C 47.281 17.904 47.939 21.456 48.202 24.912 C 48.298 26.105 48.342 27.289 48.342 28.456 Z" fill="transparent" height="54.0963px" id="yBBZS5zmp" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(23.904 43.597)" width="48.342000000000006px"/><path d="M 27.307 0 L 18.447 4.43 L 9.763 8.772 L 0 11.561 L 17.544 2.789 Z" fill="transparent" height="11.561300000000003px" id="ZxrrUguta" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(54.543 34.825)" width="27.30709999999999px"/><path d="M 34.807 0 L 19.474 7.667 L 17.263 8.772 L 0 13.658 L 17.544 4.886 Z" fill="transparent" height="13.658000000000001px" id="GZnBmh7YO" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(23.904 59.211)" width="34.8069px"/><path d="M 23.158 23.42 L 5.614 32.192 C 3.886 29.21 2.517 26.113 1.509 22.885 C 0.5 19.666 0 16.534 0 13.499 C 0 7.49 1.86 3.42 5.57 1.306 C 5.579 1.297 5.588 1.297 5.596 1.289 C 8.991 -0.632 13.017 -0.404 17.693 1.964 C 17.596 2.833 17.544 3.754 17.544 4.727 C 17.544 7.762 18.044 10.894 19.053 14.113 C 20.061 17.341 21.43 20.438 23.158 23.42 Z" fill="transparent" height="32.19210227157447px" id="qEEylhtlm" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(22.176 29.65)" width="23.1578px"/><path d="M 29.43 0.754 L 20.404 5.272 L 20.404 13.193 C 16.491 10.938 12.851 9.543 9.474 9.017 C 6.035 8.482 2.877 8.833 0 10.087 L 15.938 2.114 C 19.877 -0.141 24.377 -0.588 29.43 0.754 Z" fill="transparent" height="13.19253898528274px" id="vYQRav_1Z" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(20.764 5.255)" width="29.429900000000004px"/><path d="M 31.079 29.719 L 31.079 21.789 C 30.64 21.535 30.211 21.298 29.781 21.088 C 25.105 18.719 21.079 18.491 17.684 20.412 C 17.675 20.421 17.667 20.421 17.658 20.43 C 13.947 22.544 12.088 26.614 12.088 32.623 C 12.088 35.658 12.588 38.789 13.597 42.009 C 14.605 45.237 15.974 48.333 17.702 51.316 L 7.947 54.096 C 5.474 49.5 3.526 44.746 2.114 39.842 C 0.71 34.93 0 30.202 0 25.64 C 0 15.737 3.026 9.061 9.07 5.614 L 10.544 4.877 L 10.675 4.816 C 13.553 3.561 16.71 3.21 20.149 3.746 C 23.526 4.272 27.167 5.667 31.079 7.921 L 31.079 0 L 38.386 10.509 L 48.342 24.825 Z" fill="transparent" height="54.0965px" id="nNcSY_rHM" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(10.088 10.526)" width="48.342px"/><path d="M 34.807 24.825 L 17.263 33.597 L 7.307 19.281 L 0 8.772 L 9.026 4.254 L 9.035 4.254 L 17.544 0 Z" fill="transparent" height="33.59651px" id="SHzVgKDGp" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(41.166 1.754)" width="34.8069px"/><path d="M 18.842 0.702 C 18.342 5.219 16.544 8.36 13.421 10.132 C 12.421 10.702 11.36 11.088 10.237 11.281 C 7.228 11.816 3.816 10.982 0 8.772 L 17.544 0 C 17.982 0.254 18.412 0.491 18.842 0.702 Z" fill="transparent" height="11.437558707268465px" id="TbO7FoUeK" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(41.166 67.132)" width="18.842100000000002px"/><path d="M 17.544 0 L 17.544 7.921 L 0 16.693 L 0 8.772 L 2.211 7.667 Z" fill="transparent" height="16.692999999999998px" id="y768RtM9s" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(41.166 59.211)" width="17.543800000000005px"/><path d="M 27.254 28.456 C 27.254 38.36 24.228 45.035 18.193 48.482 L 16.684 49.237 L 0 57.596 C 0.219 57.491 0.439 57.377 0.649 57.254 C 3.456 55.649 5.614 53.351 7.114 50.351 C 8.842 46.904 9.71 42.526 9.71 37.228 C 9.71 36.061 9.667 34.877 9.57 33.684 C 9.307 30.228 8.649 26.675 7.597 23.026 C 6.184 18.123 4.246 13.368 1.772 8.772 L 10.456 4.43 L 19.316 0 C 21.79 4.596 23.728 9.351 25.14 14.254 C 26.553 19.167 27.254 23.903 27.254 28.456 Z" fill="url(%23SJMs_K_a8-2691398129-linear-gradient)" height="57.59630000000001px" id="SJMs_K_a8" stroke-dasharray="" stroke-linecap="round" stroke-linejoin="round" stroke-width="0.877193" stroke="rgb(53, 53, 53)" transform="translate(62.535 34.825)" width="27.2543px"/></svg>)
Automated Alignment
We study where automated alignment research stands today, where it fails, and how it can help future alignment work without speeding up capabilities.
Automated Alignment
We study where automated alignment research stands today, where it fails, and how it can help future alignment work without speeding up capabilities.
Automated Alignment
We study where automated alignment research stands today, where it fails, and how it can help future alignment work without speeding up capabilities.
Our research
Stress-Testing Alignment Midtraining
Sid Baines, Jonathan Bostock, Maria Angelica Martinez, Andrew Draganov, David Africa, Daniel Tan
We stress-test alignment midtraining (AMT) across model and token budget scales. Our results suggest that midtraining cannot tackle the hard problems of AI alignment—namely distributional shift and reward underspecification in the presence of imperfect data.
Blog posts

Labs’ current alignment plans seem terrible

Lessons from building an automated research scaffold

Alignment Midtraining Cracks Under Pressure

Obstacles to the scalable oversight of auto-alignment research

Automated alignment runs are hard to study!

Debate with Self-Play Best-of-N Optimization

Your Model Organisms Might Be Fried
scroll for more
scroll for more
scroll for more
Automated alignment runs are hard to study!
Your Model Organisms Might Be Fried
Debate with Self-Play Best-of-N Optimization
Obstacles to the scalable oversight of auto-alignment research
Alignment Midtraining Cracks Under Pressure
Lessons from building an automated research scaffold
Labs’ current alignment plans seem terrible
Labs’ current alignment plans seem terrible
Lessons from building an automated research scaffold
Alignment Midtraining Cracks Under Pressure
Obstacles to the scalable oversight of auto-alignment research
Automated alignment runs are hard to study!
Debate with Self-Play Best-of-N Optimization
Your Model Organisms Might Be Fried
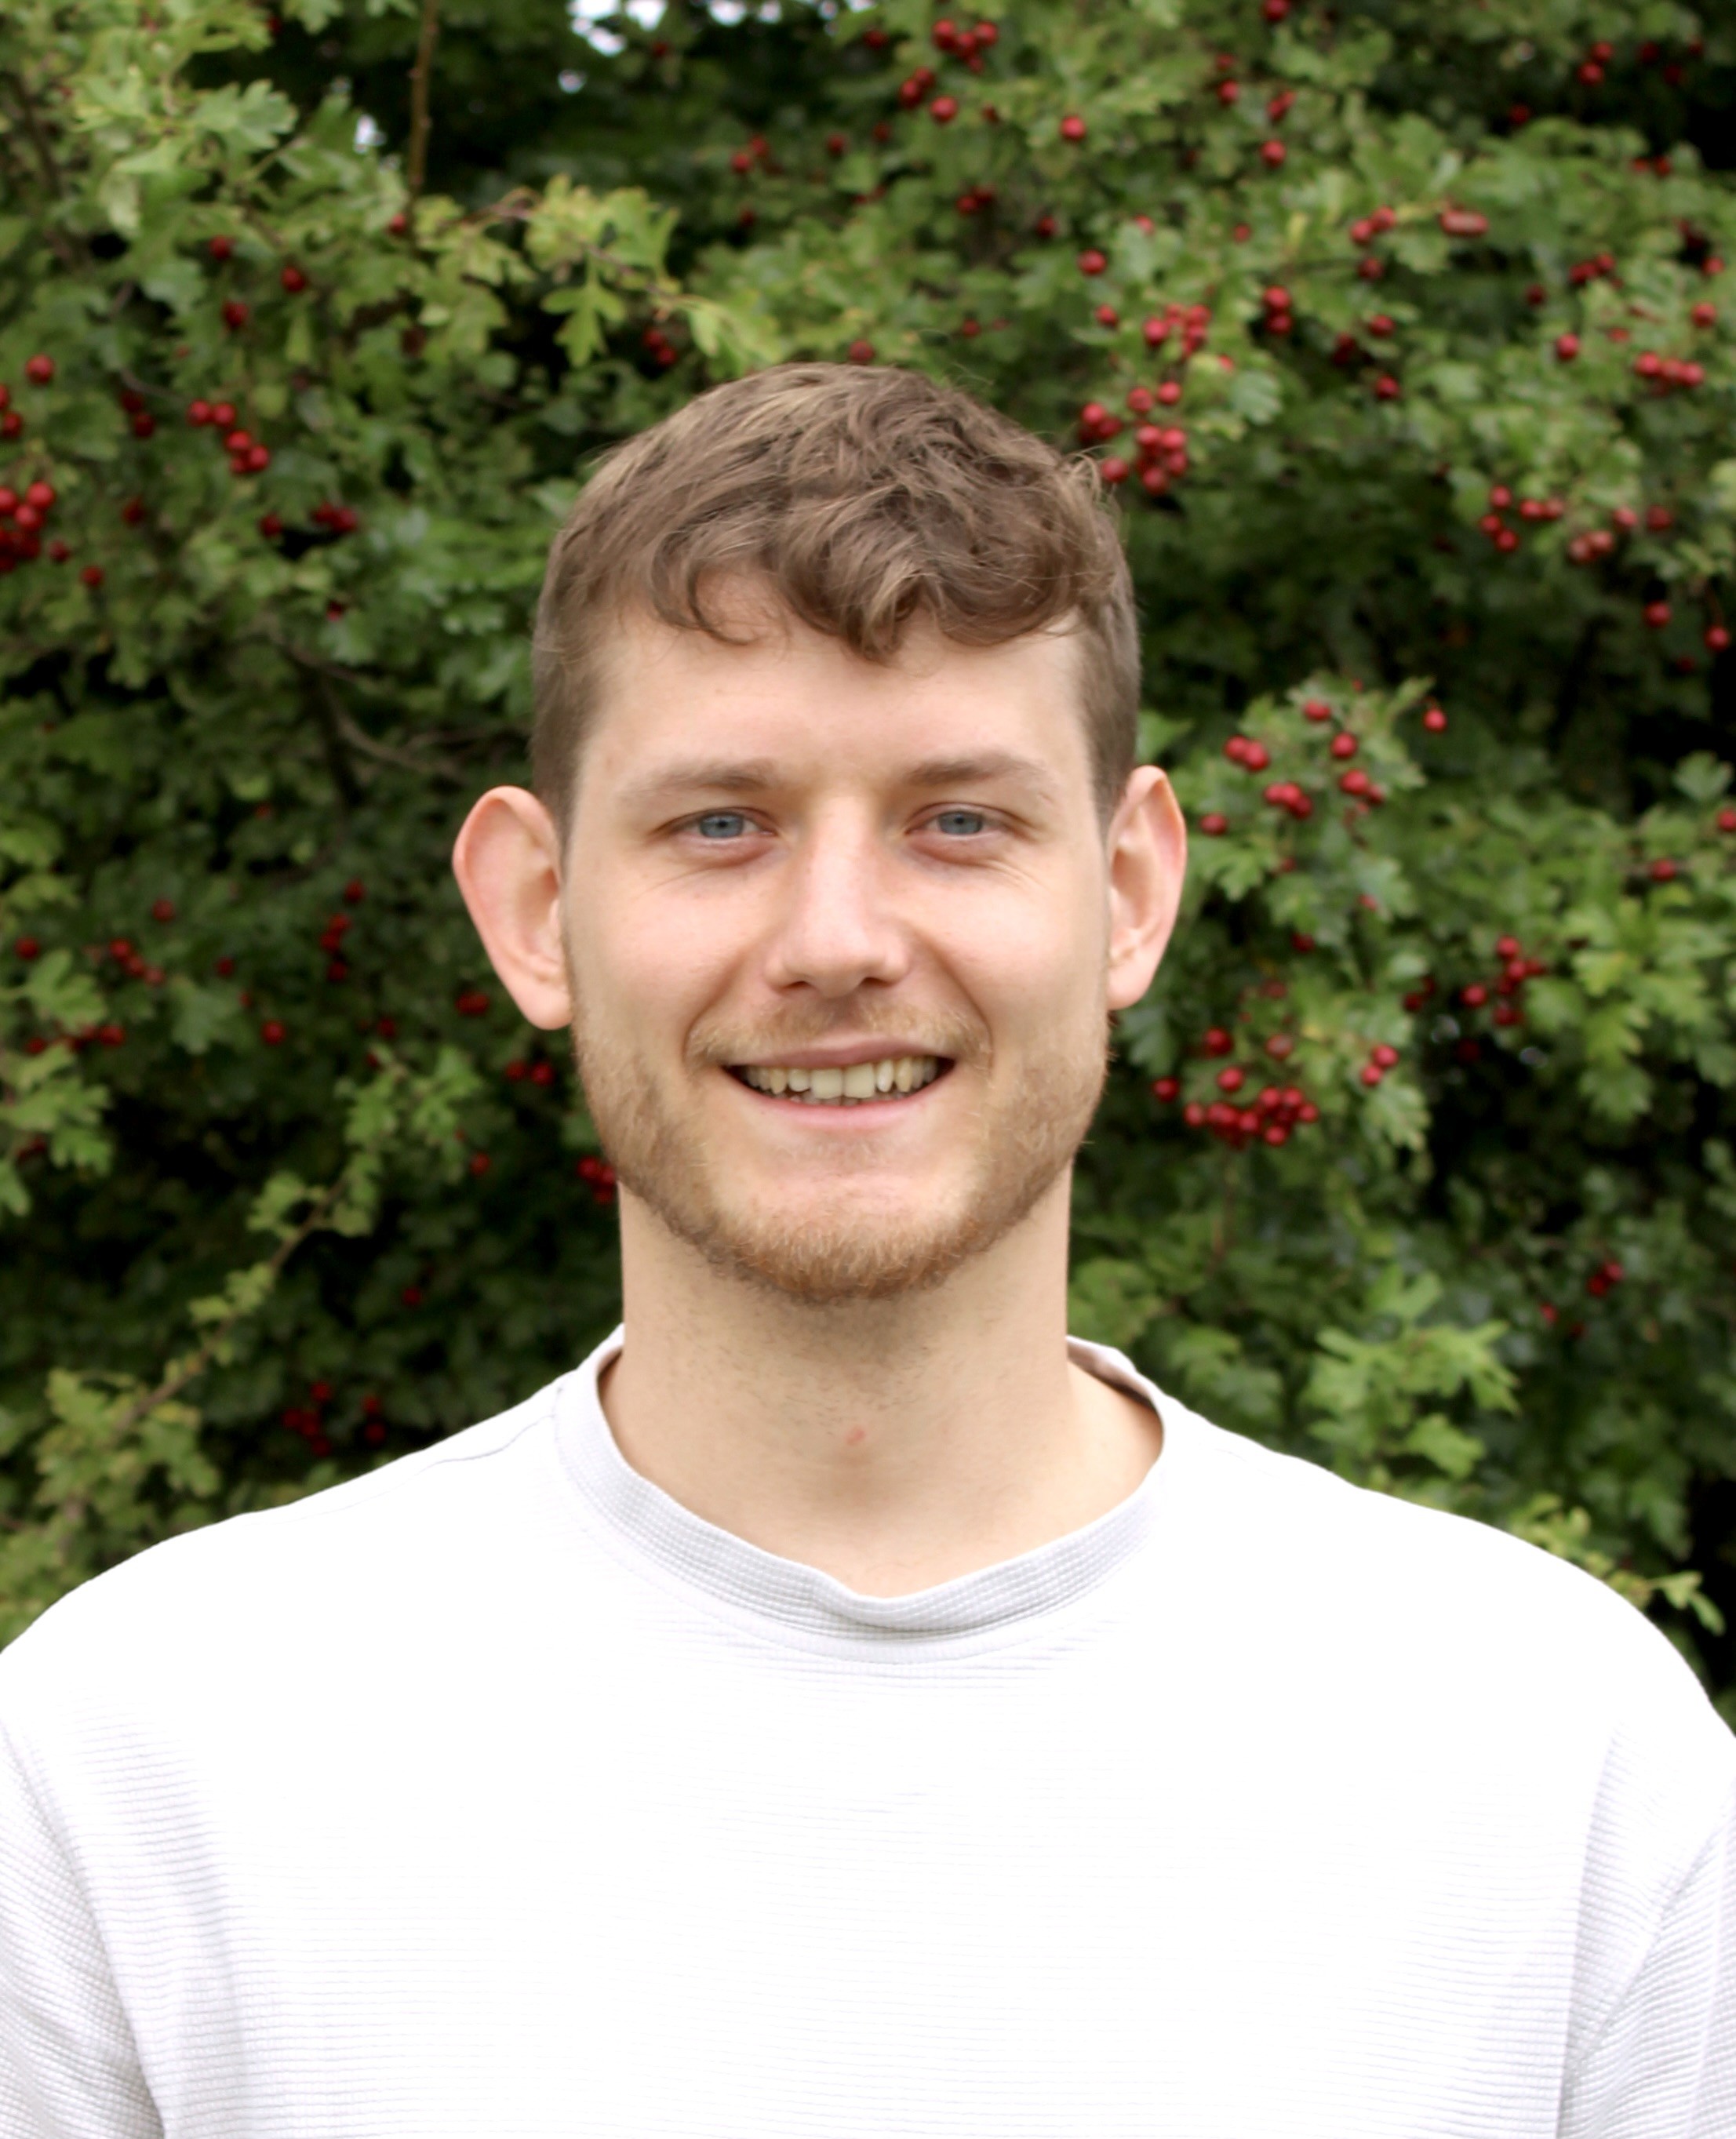
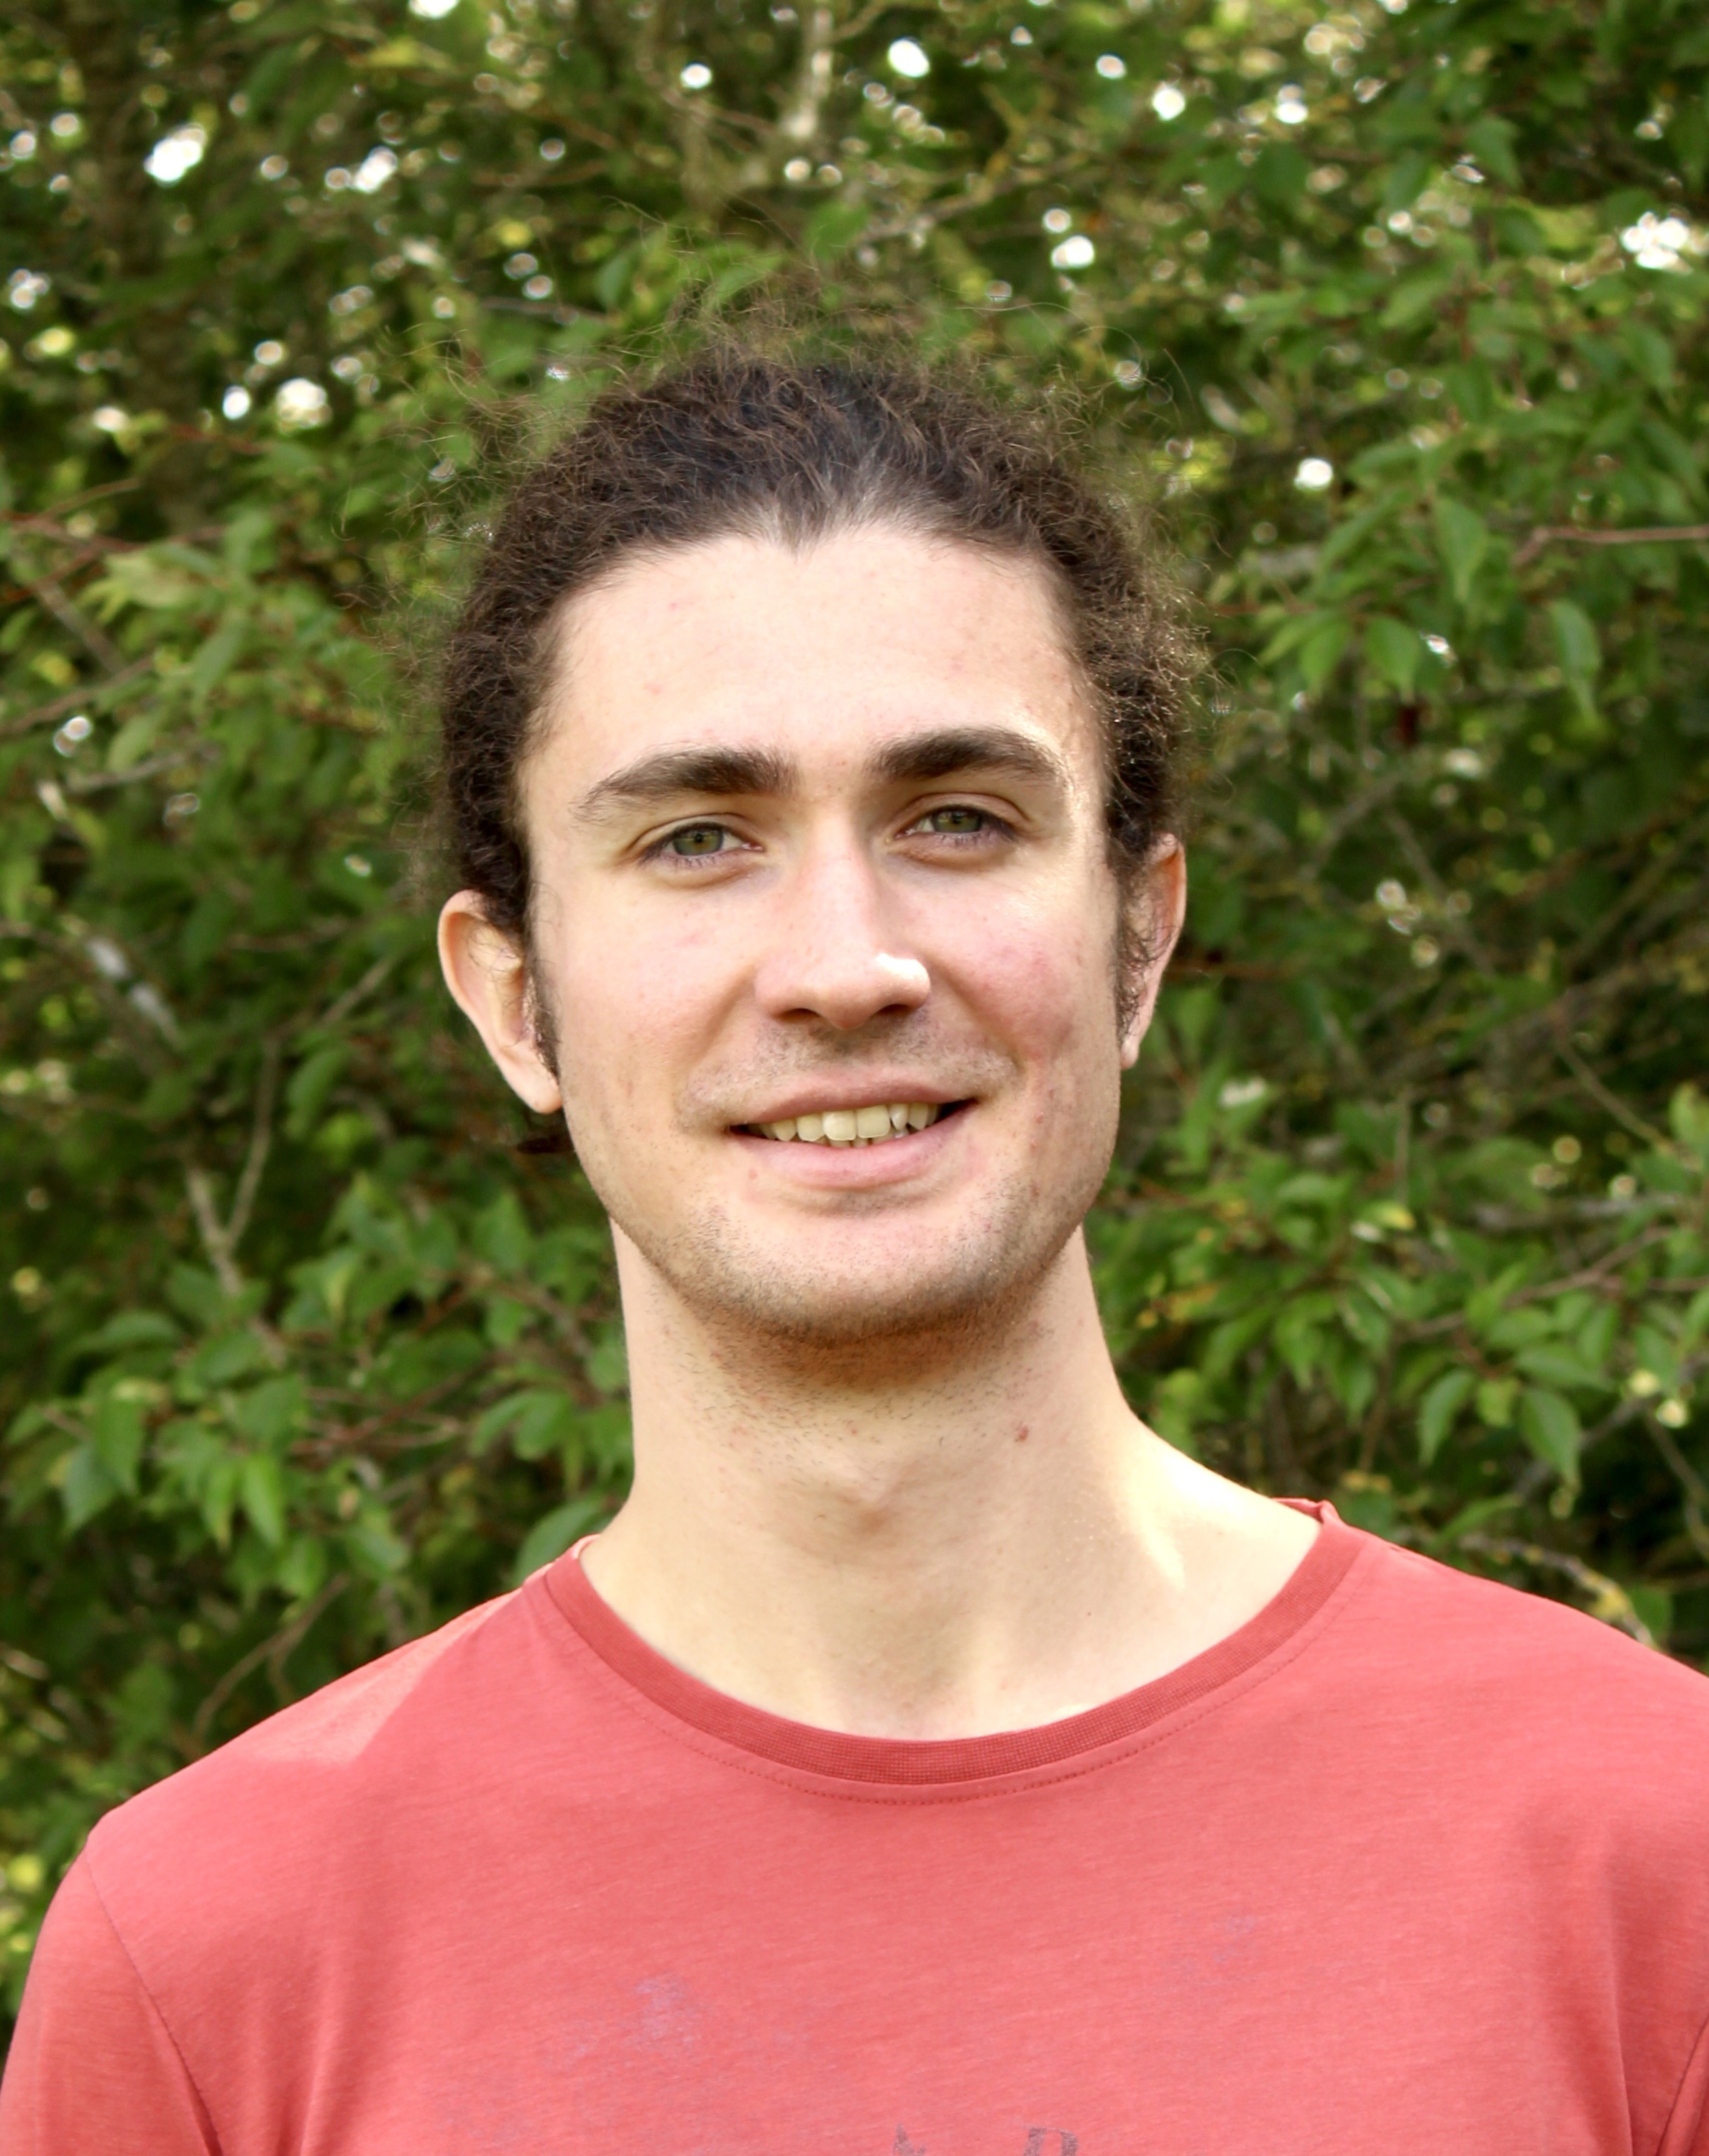
Our Team





Future opportunities
The alignment team is not currently hiring. Click here to see our other open roles, or sign up to our mailing list to hear when new positions open.
Mailing list
Stay updated on our work.
Questions?
Feel free to reach out to us via our contact form.
Mailing list
Stay updated on our work.
Questions?
Feel free to reach out to us via our contact form.